Product and engineering teams building AI-powered features face a validation challenge that traditional software testing does not fully address. Automated testing and AI evaluation systems can assess many aspects of technical performance and output quality at scale, but some issues require contextual or subject-matter judgment to determine whether an output is appropriate for its intended use.
Human review can complement automated testing by applying contextual and subject-matter judgment to AI-generated outputs, particularly where accuracy, appropriateness, or compliance cannot be reliably determined through automated evaluation alone.
For organizations preparing to release AI-enabled products or features, a structured human validation process can provide an additional layer between model testing and production. It can generate documented findings, inform release decisions, and provide a record of how AI-generated outputs were evaluated before release.
Key Takeaway
As AI-generated content becomes embedded in products and workflows, product and engineering teams need a repeatable way to evaluate output quality before release. A structured validation process establishes what should be reviewed, how outputs will be assessed, which issues require escalation, and how results will be documented, allowing teams to identify material risks before they reach users.
Effective validation also provides visibility into performance across specific use cases, where failures occur, and whether those failures create an acceptable level of risk for deployment.
Why Automated Testing and Human Validation Address Different Aspects of AI Quality
Automated testing frameworks can confirm that an AI system functions as designed. They can assess outputs against predefined parameters, flag content that violates defined rules, and run consistency checks across large input sets efficiently and at scale. Modern AI evaluation systems can also automate assessment of certain qualitative characteristics, including aspects of factuality, safety, and bias.
Human review adds contextual and subject-matter judgment that automated evaluation may not fully capture. A legally plausible response may contain a subtle jurisdictional error. A healthcare response may omit a material safety qualification. A financial explanation may reach an inappropriate conclusion while relying on accurate underlying information.
These types of issues can require a reviewer who understands the standards governing the specific use case, not just the technical parameters of the AI system.
Automated testing and human review can therefore serve complementary functions, with human review directed toward output types and risk categories where contextual or subject-matter judgment provides additional value.
Define Validation Standards Before Review Begins
A meaningful validation process starts with clearly defined standards. Before review begins, product teams should establish what constitutes an acceptable output and how reviewers should apply those standards consistently.
For regulated or specialized applications, those standards may incorporate legal, regulatory, clinical, financial, technical, or other subject-matter requirements relevant to the product and its intended use. Defining the standards in advance provides a consistent foundation for reviewer decisions, issue classification, escalation, and documentation.
Apply Review Based on Risk
Not every AI-generated output carries the same potential consequence.
A low-risk internal summary may warrant a different level of review than an output used in a customer-facing healthcare, legal, or financial application. Validation can therefore be designed around the risk profile of the product and the outputs it generates.
Teams can segment outputs by factors such as intended use, audience, subject matter, potential impact of an error, degree of reliance, and regulatory sensitivity. Higher-risk categories may warrant comprehensive human review, while lower-risk categories may be evaluated through structured sampling or other quality-control methodologies.
This allows organizations to direct human expertise toward areas where errors could have greater consequences without applying the same level of review uniformly across every output type.
Defining AI Output Validation Criteria
A structured validation process begins with defined criteria for evaluating AI-generated outputs. The criteria should reflect the product’s use case, intended users, applicable standards, and the potential risks associated with inaccurate or inappropriate content.
Depending on the use case, evaluation criteria may include:
- Factual accuracy and completeness: Whether outputs are factually correct, claims are adequately supported, and material information required by the defined review standard is present.
- Hallucinations and unsupported claims: Whether outputs contain fabricated information, invented citations, unsupported conclusions, or claims presented without an adequate basis.
- Bias and fairness: Where relevant, whether outputs exhibit patterns of differential treatment, rely on assumptions that may affect particular populations, or produce materially different results across comparable inputs.
- Regulatory and compliance alignment: For regulated use cases, whether outputs align with the standards identified as applicable to the content and workflow.
- Tone, safety, and appropriateness: Whether outputs are appropriate for the intended user and context and meet the product’s defined content and safety standards.
These criteria can be tailored to the specific product and use case, creating a consistent framework for evaluating outputs and documenting findings.
Establish a Consistent Review Methodology
Once standards and risk levels are defined, the review itself needs to be repeatable.
Reviewers should work from a common set of criteria and use consistent classifications for the issues they identify. A validation framework might categorize errors by type, severity, or potential impact and define when an issue warrants correction, escalation, or additional investigation.
Consistency becomes especially important when multiple reviewers or teams are involved. A standardized methodology can make it easier to compare findings, identify recurring patterns, and evaluate performance across a larger output population.
For specialized content, reviewer qualifications should align with the subject matter being evaluated. Some outputs can be assessed through general quality review, while others may require trained professionals or subject-matter experts to determine whether the information is substantively correct.
Document Findings and Resolution
Identifying an error is only part of the validation process. Teams also need a record of what was reviewed, the standards applied, the issues identified, and how those issues were resolved.
Documentation may include:
- Outputs or samples reviewed
- Evaluation criteria applied
- Reviewer roles or qualifications
- Issues identified
- Issue classifications or severity levels
- Escalation decisions
- Corrective actions
- Final disposition
Structured documentation can help product and engineering teams identify recurring failure patterns, evaluate whether corrective measures are working, and support internal governance or audit processes where applicable.
Findings can also inform changes to prompts, retrieval sources, model configurations, guardrails, training data, source materials, or product workflows before release. This connects human validation directly to product development by making review findings a structured input to engineering and product decisions rather than solely a final approval step.
Integrate Validation Into the Release Cycle
Validation can be incorporated into existing development and release processes rather than treated solely as a final approval step.
Teams can establish defined validation checkpoints during development, pre-release testing, and subsequent product updates. New models, material changes to prompts or data sources, and expansion into different or higher-risk use cases may warrant additional review.
The appropriate threshold for release will vary by product, use case, and organizational risk tolerance. Defining that threshold in advance gives teams a consistent basis for determining whether identified issues have been sufficiently addressed.
This creates a repeatable workflow:
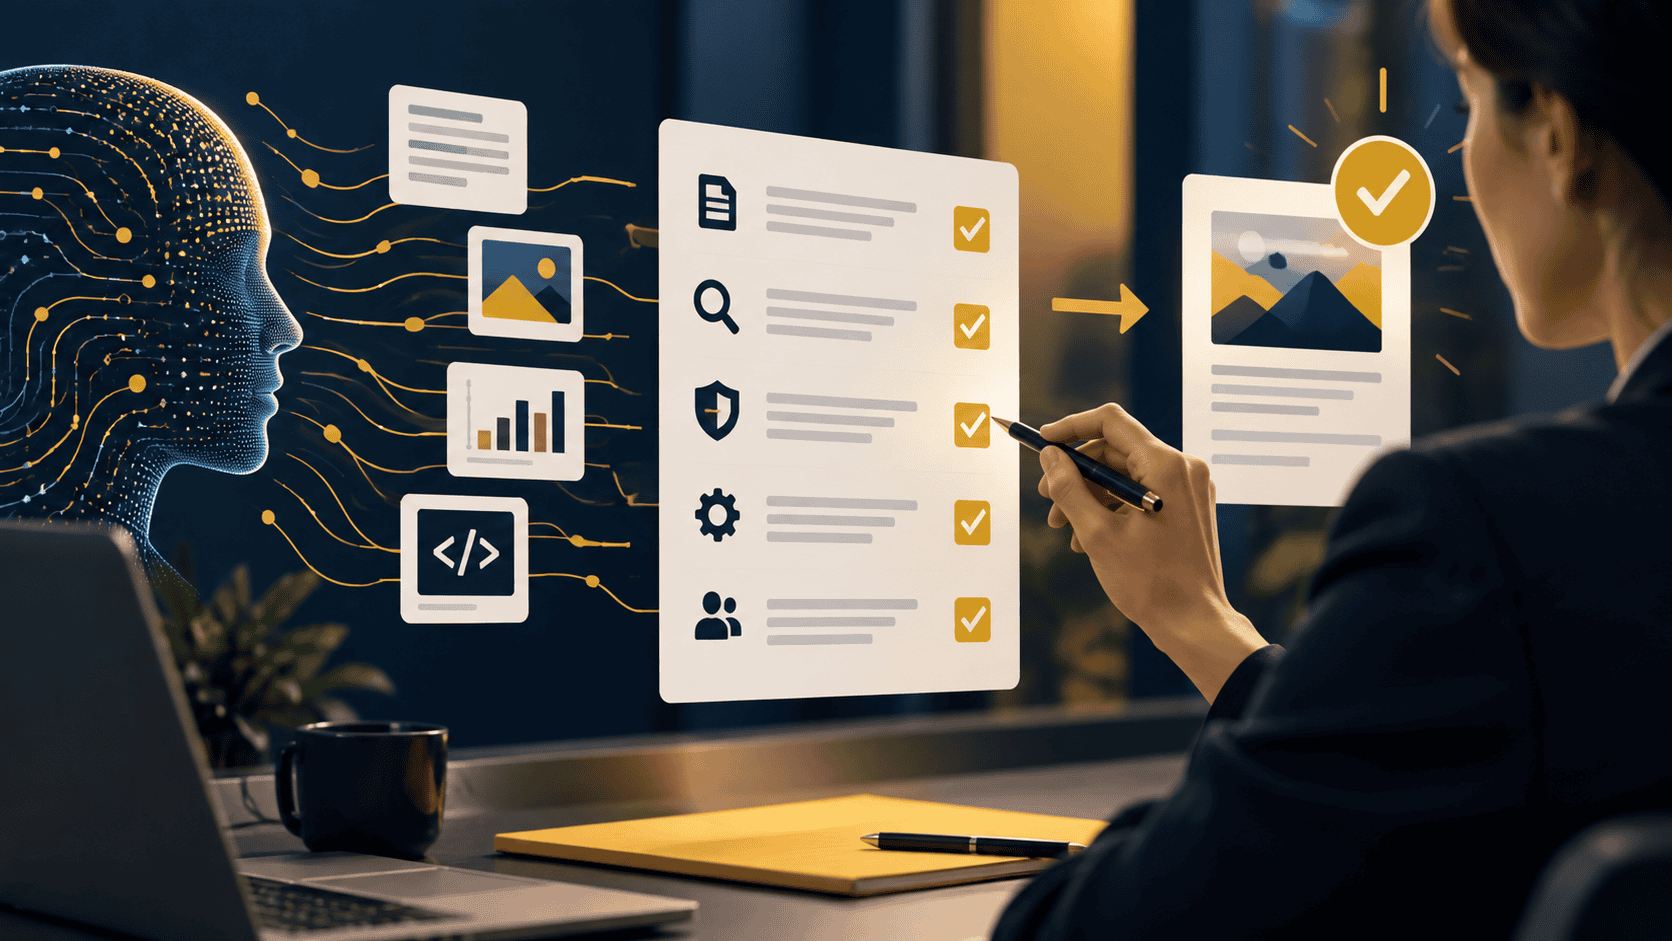
Define the standard → assess risk → review outputs → classify findings → resolve material issues → document results → release.
Regulatory and Governance Frameworks for AI Validation
Established AI risk frameworks provide additional context for incorporating testing and validation throughout the AI lifecycle, although their applicability and requirements differ.
The voluntary NIST AI Risk Management Framework (AI RMF) addresses testing, evaluation, documentation, and ongoing measurement as components of AI risk management. Its measure function calls for AI systems to be tested before deployment and regularly while in operation. The accompanying NIST AI RMF Playbook provides suggested actions for implementing the framework, including human review as one approach for evaluating unexpected data and the reliability of generated outputs.
The EU AI Act establishes legal requirements for AI systems classified as high-risk under the regulation. Article 9 requires testing as part of the risk-management process and provides that testing should occur, as appropriate, throughout development and before a high-risk AI system is placed on the market or put into service. Testing must use predefined metrics and probabilistic thresholds appropriate to the system’s intended purpose.
Whether these requirements apply depends on the AI system, its intended purpose, and its classification under the regulation.
Extend Validation Beyond Product Release
For products that continue generating outputs after deployment, the same validation framework can support ongoing evaluation. Changes in models, prompts, retrieval sources, underlying data, user behavior, or operating conditions may affect system performance over time.
Structured production monitoring and sampling can help identify emerging issues, recurring patterns, and differences between pre-release testing and real-world performance. Findings from ongoing validation can then provide structured feedback to product, engineering, risk, and compliance teams and inform prompt updates, model adjustments, retrieval configuration changes, guardrail improvements, and other product changes.
Supporting Product and Engineering Teams
Baer Reed’s Human-in-the-Loop Validation services provide scalable review by qualified professionals, structured quality-control processes, and audit-ready reporting that can be integrated into AI development and release workflows. Contact Baer Reed to learn how our validation services can support pre-release testing and ongoing quality review for AI-enabled products.
FAQs
Teams can validate AI-generated outputs by defining acceptance criteria, determining an appropriate risk-based review methodology, selecting outputs for evaluation, applying consistent review standards, documenting identified issues, and establishing thresholds for correction or escalation before release. The specific criteria and review depth should reflect the risk profile of the product and the standards governing its use case.
Read More: Human-in-the-Loop Validation: The Operational Layer for Regulated AI Deployment
Not necessarily. The appropriate level of review depends on the risk associated with the product and its outputs. Higher-risk applications may warrant comprehensive review, while lower-risk use cases may be evaluated through structured sampling or other quality-control methodologies.
Read More: AI Output Validation and Oversight Services
Reviewer qualifications should correspond to the content and level of risk involved. General quality issues may be evaluated by trained reviewers, while legal, healthcare, financial, scientific, technical, or other specialized outputs may require relevant subject-matter expertise.
Read More: Quality Assurance in Legal AI: Validating Models, Preventing Drift
Validation can be incorporated at multiple points, including during development, before product release, after material changes to models or workflows, and as part of ongoing post-release monitoring. The appropriate validation checkpoints depend on the product, use case, and risk profile.
Read More: Human-in-the-Loop Validation: The Operational Layer for Regulated AI Deployment
Documentation may include the outputs or samples reviewed, evaluation criteria, reviewer roles or qualifications, identified issues, severity classifications, escalation decisions, corrective actions, and final disposition. The appropriate documentation will depend on the validation program and the organization’s governance requirements.
Read More: AI Output Validation and Oversight Services